Tech riderRev. 20 Sept 2026
LiveBench
- 1Runs onLinux, Mac, Web, Windows
- 2CostsNot stated by the maker
- 3Deployment optionsboth
- 4LLM-as-a-judgeNo
3 lines stated Written from the maker's own pages: livebench.ai
Overview
LiveBench is ranked #9 of 29 in LLM evaluation tools on Specifiction. It runs on Linux, macOS, Web, Windows.
Compared on LLM evaluation tools
- Deployment options
- bothlivebench.ai
- LLM-as-a-judge
- Nolivebench.ai
Facts
- Product
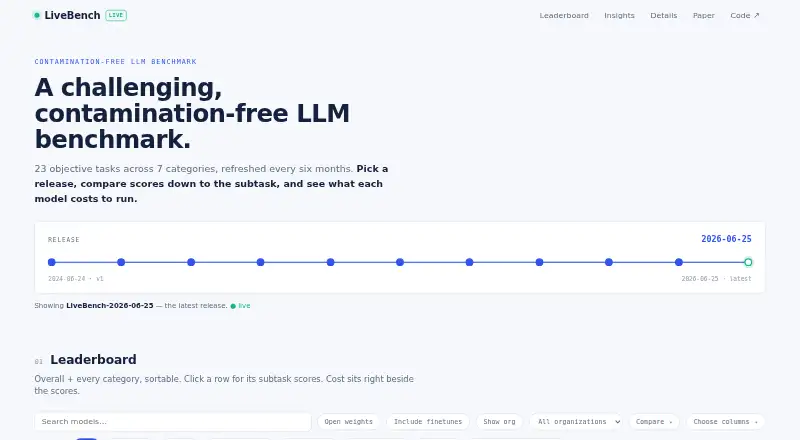
- LiveBench is described as a challenging, contamination-free LLM benchmark.livebench.ai · 4 Oct 2026
- Benchmark scope
- The current site describes 23 objective tasks across 7 categories, refreshed every six months.livebench.ai · 4 Oct 2026
- Categories
- The site lists Reasoning, Coding, Agentic Coding, Mathematics, Data Analysis, Language, and Instruction Following.livebench.ai · 4 Oct 2026
- Leaderboard
- The leaderboard shows overall and category scores, with model rows expandable to subtask scores.livebench.ai · 4 Oct 2026
- Insights
- Insights include quality-versus-cost, ranked cost, and category profile views.livebench.ai · 4 Oct 2026
- Cost metric
- The site defines cost per successful task as (Σ cost ÷ Σ questions ÷ score) × 100 over the selected scope.livebench.ai · 4 Oct 2026
- Contamination controls
- The project README says it limits potential contamination with newly released questions and questions based on recent datasets, papers, news, and movie synopses.github.com · 4 Oct 2026
- Scoring
- The README says questions have verifiable objective ground-truth answers and can be scored automatically without an LLM judge.github.com · 4 Oct 2026
- Open source
- The project publishes its code in a public GitHub repository and links to benchmark data on Hugging Face.github.com · 4 Oct 2026
- Run evaluations
- The README documents a Python command-line pipeline for generating model answers, scoring them, and displaying results.github.com · 4 Oct 2026
- Model compatibility
- The README says OpenAI-compatible API endpoints can be used and lists implemented inference support for Anthropic, Cohere, Mistral, Together, and Google models.github.com · 4 Oct 2026
- Local models
- The README says local model inference is unmaintained and recommends serving models through an OpenAI-compatible API using vLLM.github.com · 4 Oct 2026
- Agentic coding requirements
- The README says evaluating agentic coding tasks requires Docker and that storing the task-specific images may take up to 150 GB.github.com · 4 Oct 2026
- Support
- The README directs users to open a GitHub issue or email [email protected] for model evaluation support.github.com · 4 Oct 2026
Best LiveBench alternatives
See all 20 All accessCh 01 Promptfoo Free planAPILinux Free to start7.6 All accessCh 02 DeepEval Free planLinuxMac Free to start7.4 All accessCh 03 Maxim AI Free planFree trialAPI from $29/mo7.4 All accessCh 04 Giskard Free planAPILinux Free to start7.2 All accessCh 05 Braintrust Free planAPIself-hosted from $249/mo7.1 All accessCh 06 Galileo Free planAPIself-hosted from $100/mo7.1
Where it ranks on Specifiction
Is LiveBench yours?
Claim it for free: prove the domain, then correct facts, plans and screenshots. An editor reviews every change.
Sources
- livebench.ai· checked 4 Oct 2026
- livebench.ai· checked 4 Oct 2026
- github.com/LiveBench/LiveBench· checked 4 Oct 2026