Tech riderRev. 5 Oct 2026
- 1Runs onLinux, self-hosted
- 2CostsFree plan
- 3Voice cloningYes
- 4Audio upload formatsWAV, MP3, FLAC
- 5Export formatsWAV
5 lines stated Written from the maker's own pages: github.com
Overview
Amphion is ranked #119 of 222 in text-to-speech tools on Specifiction. It runs on Linux, Self-hosted. There is a free plan.
Amphion plans and pricing
All plansCompared on text-to-speech tools
- Free plan
- Yesgithub.com
- Voice cloning
- Yesgithub.com
- Audio upload formats
- WAV, MP3, FLACgithub.com
- Export formats
- WAVgithub.com
Facts
- Purpose
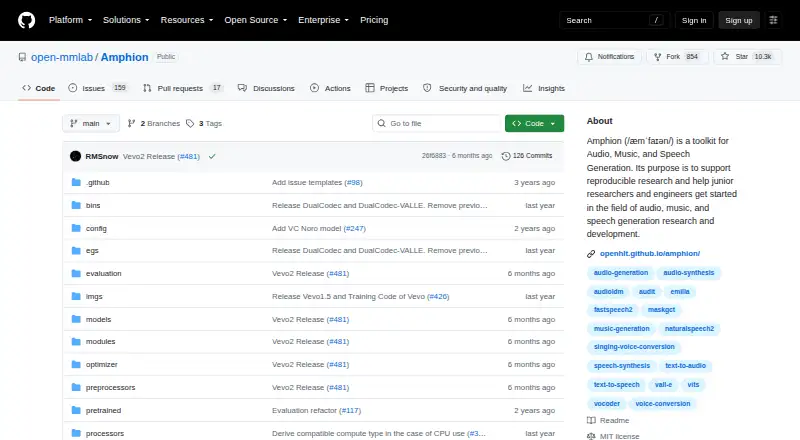
- Amphion is an open-source toolkit for audio, music, and speech generation aimed at supporting reproducible research and helping junior researchers and engineers get started.github.com · 4 Oct 2026
- Generation tasks
- Supported tasks include text-to-speech, singing voice synthesis, voice conversion, accent conversion, singing voice conversion, and text-to-audio; text-to-music is listed as in development.github.com · 4 Oct 2026
- Voice and speech models
- The toolkit includes architectures such as FastSpeech2, VITS, VALL-E, NaturalSpeech2, MaskGCT, and Vevo-TTS for text-to-speech, plus Vevo, FACodec, and Noro for voice conversion.github.com · 4 Oct 2026
- Singing generation
- Vevo2 supports controllable speech and singing generation, including voice conversion, singing voice conversion, singing voice editing, singing style conversion, and melody control.github.com · 4 Oct 2026
- Text to audio
- Amphion supports text-to-audio generation using a latent diffusion model and describes it as the official implementation of the text-to-audio generation part of its NeurIPS 2023 paper.github.com · 4 Oct 2026
- Audio evaluation
- It provides objective evaluation metrics for F0 and energy modeling, intelligibility, spectrogram distortion, and speaker similarity.github.com · 4 Oct 2026
- Visualization
- Amphion includes interactive visualizations of classic model processing, including SingVisio for the diffusion model used in singing voice conversion.github.com · 4 Oct 2026
- Dataset preprocessing
- It unifies preprocessing for multiple open-source audio datasets and supports the Emilia dataset and Emilia-Pipe pipeline for in-the-wild speech data.github.com · 4 Oct 2026
- Integrations and dependencies
- The project lists WeNet, Whisper, and ContentVec among pretrained models used for content-based features, and its Docker instructions require NVIDIA drivers, NVIDIA Container Toolkit, and CUDA.github.com · 4 Oct 2026
- Installation
- The README documents setup using Python 3.9.15 with Conda or a Docker image, and the Docker instructions require mounting the dataset into the container.github.com · 4 Oct 2026
- License and cost
- Amphion is licensed under MIT and the README says it is free for research and commercial use.github.com · 4 Oct 2026
- Support and community
- The project invites contributions and links to a Discord channel for community engagement.github.com · 4 Oct 2026
- Supported tasks
- The README marks text-to-speech, singing voice synthesis, voice conversion, accent conversion, singing voice conversion, and text-to-audio as supported, while text-to-music is in development.github.com · 5 Oct 2026
- Datasets
- Amphion unifies preprocessing for several open-source datasets and supports the Emilia dataset and Emilia-Pipe for in-the-wild speech data.github.com · 5 Oct 2026
- Models
- The toolkit implements diffusion, transformer, VAE, and flow-based model architectures.github.com · 5 Oct 2026
- External model tools
- For content-based features, the README lists pretrained models including WeNet, Whisper, and ContentVec.github.com · 5 Oct 2026
- Docker requirement
- The Docker instructions call for Docker, an NVIDIA Driver, NVIDIA Container Toolkit, and CUDA, and state that mounting the dataset with -v is necessary.github.com · 5 Oct 2026
- License
- Amphion is released under the MIT License and is stated to be free for research and commercial use.github.com · 5 Oct 2026
- Intended users
- The project describes itself as supporting reproducible research and helping junior researchers and engineers enter audio, music, and speech generation research and development.github.com · 5 Oct 2026
- Technical limit
- Text-to-music is listed as in development rather than supported.github.com · 5 Oct 2026
Best Amphion alternatives
See all 20 All accessCh 01 Typecast Free planFree trialAndroid from $5/mo9.1 All accessCh 02 Google Cloud Text-to-Speech Free planFree trialAPI from $16/mo8.9 All accessCh 03 Voicebox Free planAndroidAPI from $1/mo8.8 All accessCh 04 Fish Audio Free planAPILinux from $11/mo8.7 All accessCh 05 NaturalReader AndroidBrowser from $6.58/mo8.7 All accessCh 06 Speechify Free planAndroidAPI from $29/mo8.7
Where it ranks on Specifiction
- Best Text-To-Speech Tools in 2026#119 of 222
- Best AI Voice Changers in 2026#35 of 87
Is Amphion yours?
Claim it for free: prove the domain, then correct facts, plans and screenshots. An editor reviews every change.
Sources
- github.com/open-mmlab/Amphion· checked 4 Oct 2026